Key details for this exam, checked against the published exam outline
Each question shows the correct answer and an explanation of why it is right
What is the recommended approach to collect data from network devices?
The recommended approach to collect data from network devices is to use a Syslog server with a Universal Forwarder (UF) installed. The network devices send data to the Syslog server, which then forwards the data to Splunk Cloud using the Universal Forwarder. This method ensures reliable data ingestion and processing while maintaining flexibility in handling different types of network device data.
Splunk Documentation Reference: Best practices for getting data in
Which of the following is the default bandwidth limit in the Splunk Universal Forwarder credentials package?
The default bandwidth limit in the Splunk Universal Forwarder is set to 256 KBps. This setting is in place to prevent the forwarder from overwhelming network resources, and it can be adjusted as necessary based on the deployment's specific needs.
Splunk Documentation Reference: Universal Forwarder Configuration
Which of the following are features of a managed Splunk Cloud environment?
In a managed Splunk Cloud environment, several features are available to ensure that the platform is secure, scalable, and meets enterprise requirements. The key features include:
Availability of premium apps: Splunk Cloud supports the installation and use of premium apps such as Splunk Enterprise Security, IT Service Intelligence, etc.
SSO Integration: Single Sign-On (SSO) integration is supported, allowing organizations to leverage their existing identity providers for authentication.
IP address whitelisting and blacklisting: To enhance security, managed Splunk Cloud environments allow for IP address whitelisting and blacklisting to control access.
Given the options:
Option C correctly lists these features, making it the accurate choice.
Option A incorrectly states 'no IP address whitelisting or blacklisting,' which is indeed available.
Option B mentions 'no SSO integration' and 'no availability of premium apps,' both of which are inaccurate.
Option D talks about a 'maximum concurrent search limit of 20,' which does not represent the standard limit settings and may vary based on the subscription level.
Splunk Documentation Reference:
Splunk Cloud Features and Capabilities
Single Sign-On (SSO) in Splunk Cloud
Security and Access Control in Splunk Cloud
What is the correct syntax to monitor /apache/too/logo, /apache/bor/logs, and /apache/bar/l/logo?
A)
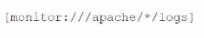
B)

C)
D)

In the context of Splunk, when configuring data inputs to monitor specific directories, the correct syntax must match the directory paths accurately and adhere to the format recognized by Splunk.
Option A: [monitor:///apache/*/logs] - This syntax would attempt to monitor all directories under /apache/ that contain the word logs, which is not what the question is asking. It is incorrect for the paths given in the question.
Option B: [monitor:///apache/foo/logs, /apache/bar/logs, /apache/bar/1/logs] - This syntax correctly lists the specific paths /apache/foo/logs, /apache/bar/logs, and /apache/bar/1/logs separately. This is the correct answer as it precisely matches the paths given in the question.
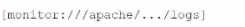
Option C: [monitor:///apache/.../logs] - The triple dots syntax (...) is used to match any subdirectories under /apache/. This would monitor all logs directories within any subdirectory structure under /apache/, which again, does not specifically match the paths given in the question.
Option D: [monitor:///apache/foo/logs, /apache/bar/logs, and /apache/bar/1/logs] - This syntax includes the word 'and', which is not valid in the Splunk monitor stanza. The syntax should list the paths separated by commas, without additional words.
Thus, Option B is the correct syntax to monitor the specified paths in Splunk.
For additional reference, you can check the official Splunk documentation on monitoring inputs which provides guidelines on how to configure monitoring of files and directories.
Which of the following tasks is not managed by the Splunk Cloud administrator?
In Splunk Cloud, several administrative tasks are managed by the Splunk Cloud administrator, but certain tasks related to the underlying infrastructure and core software management are handled by Splunk itself.
B . Upgrading the indexer's Splunk software is the correct answer. Upgrading Splunk software on indexers is a task that is managed by Splunk's operations team, not by the Splunk Cloud administrator. The Splunk Cloud administrator handles tasks like forwarding events, managing knowledge objects, and creating users and roles, but the underlying software upgrades and maintenance are managed by Splunk as part of the managed service.
Splunk Documentation Reference:
Splunk Cloud Administration
Which of the following is not considered a best practice for the deployment server?
In Splunk, it's considered best practice to create small, single-purpose deployment apps rather than large, multi-purpose ones. This approach ensures better manageability, easier updates, and clearer version control. Option D, which suggests creating large, multi-purpose deployment apps, is not a best practice.
Splunk Documentation Reference: Deployment Server Best Practices
At what point in the indexing pipeline set is SEDCMD applied to data?
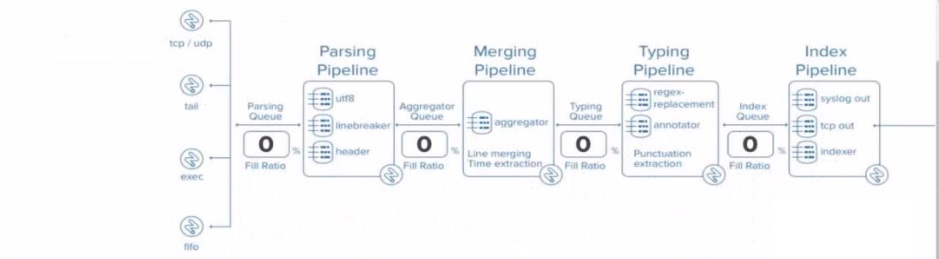
In Splunk, SEDCMD (Stream Editing Commands) is applied during the Typing Pipeline of the data indexing process. The Typing Pipeline is responsible for various tasks, such as applying regular expressions for field extractions, replacements, and data transformation operations that occur after the initial parsing and aggregation steps.
Here's how the indexing process works in more detail:
Parsing Pipeline: In this stage, Splunk breaks incoming data into events, identifies timestamps, and assigns metadata.
Merging Pipeline: This stage is responsible for merging events and handling time-based operations.
Typing Pipeline: The Typing Pipeline is where SEDCMD operations occur. It applies regular expressions and replacements, which is essential for modifying raw data before indexing. This pipeline is also responsible for field extraction and other similar operations.
Index Pipeline: Finally, the processed data is indexed and stored, where it becomes available for searching.
Splunk Cloud Reference: To verify this information, you can refer to the official Splunk documentation on the data pipeline and indexing process, specifically focusing on the stages of the indexing pipeline and the roles they play. Splunk Docs often discuss the exact sequence of operations within the pipeline, highlighting when and where commands like SEDCMD are applied during data processing.
Source:
Splunk Docs: Managing Indexers and Clusters of Indexers
Splunk Answers: Community discussions and expert responses frequently clarify where specific operations occur within the pipeline.
Exam domains verified against: Official Splunk SPLK-1005 exam guide, last checked October 2026.
Cloud topology and tasks managed by the Splunk cloud administrator. Focuses on primary differences between Splunk Cloud and Splunk Enterprise to understand platform-specific administration approaches.
Definition of a Splunk index and characteristics of indexes in cloud environments. Covers monitoring indexing activities and retrieving data from indexes.
Administration of Splunk user roles and responsibility assignments. Focuses on integrating Splunk with LDAP for enterprise authentication.
Sample question from this domain above: Q4
Configuration files and directories in Splunk environments. Covers configuration precedence and sub-topics related to index time and search time processes.
Sample question from this domain above: Q3
Splunk forwarder types and the role of forwarders in data ingestion. Configuration of a forwarder to Splunk Cloud and testing forwarder connections.
Splunk Deployment Server and the use of forwarder management. Configuration of forwarders as deployment clients and management through deployment apps.
Splunk process for inputting data and how data flows through Splunk. Creating file and directory monitor inputs to capture data from various sources.
Sample question from this domain above: Q2
Creating network inputs using TCP and UDP protocols. Creating basic scripted inputs and identifying Windows input types and their uses.
Default processing during the input phase. Configuration of input phase options such as source type fine-tuning and character set encoding.
Default processing during parsing and event line breaking optimization. How timestamps and time zones are extracted or assigned to events. Using data preview to validate event creation.
Data transformations and how they are invoked. Using transformations with props.conf and transforms.conf to modify raw data and SEDCMD for data manipulation.
Sample question from this domain above: Q6
Process for installing apps in Splunk Cloud. Understanding private apps and how they are managed within Splunk environments.
How to isolate problems before contacting Splunk Cloud Support. Defining the process and best practices for working with Splunk Cloud Support.
Sample question from this domain above: Q1
Common questions about the exam itself

