Key details for this exam, checked against the published exam outline
Each question shows the correct answer and an explanation of why it is right
Your customer noticed in NetApp Active IQ that their NetApp Cloud Volumes ONTAP for Azure HA solution is no longer sending AutoSupport messages over HTTPS. A support ticket has been opened to find out why. No changes have been made to the Cloud Volumes ONTAP for Azure HA environment.
In this scenario, which two autosupport command parameters should be used to validate that AutoSupport Is working properly? {Choose two.)
= The -transport parameter specifies the protocol used to send AutoSupport messages, which should be HTTPS by default. The -proxy-url parameter specifies the proxy server used to send AutoSupport messages, which should be the Connector's IP address and port if the Cloud Volumes ONTAP nodes do not have outbound internet access. These two parameters can be used to check the AutoSupport configuration and connectivity status.Reference=Verify AutoSupport setup,Troubleshoot your AutoSupport configuration,High-availability pairs in Azure
A system panic due to an "L2 watchdog timeout hard reset" error occurred. You have found a FIFO message in the SP log.
Which FIFO message Is useful for Investigating this Issue?
= The FIFO message before NMI is useful for investigating the issue because it shows the state of the system before the non-maskable interrupt (NMI) was triggered by the L2 watchdog timeout. The FIFO message contains information about the CPU registers, the stack pointer, the instruction pointer, and the last executed instructions. This can help identify the cause of the system hang or deadlock that led to the watchdog reset. The other FIFO messages are not useful because they show the state of the system after the reset or shutdown, which may not reflect the original problem.Reference=https://kb.netapp.com/onprem/ontap/hardware/Handling_L2_Watchdog_Resets_on_the_FAS8200_and_AFF_A300_platforms
https://docs.netapp.com/us-en/ontap-metrocluster/install-ip/task_sw_config_restore_defaults.html
The motherboard of Node-01 is being replaced. To perform this task, a takeover was Initiated from Node-02. Node-02 panics showing the string below.
PANIC; Permanent errors on all HA mailbox disks (while marshalling header) in SKprocess fnmbx_instanceWorker on release 9.5P8 (C)
What has happened in this situation?
The mailbox disks are the first two disks of the root aggregate on each node of an HA pair. They store the HA state information and the panic dump files.The mailbox disks are used for communication between the HA partners and for takeover and giveback operations1
The mailbox destroy local command is used to destroy the mailbox disks on the local node. This command is only available in maintenance mode and should be used with extreme caution.The command is intended for situations where the mailbox disks are corrupted or inaccessible and need to be recreated2
If the mailbox destroy local command is executed on a node that is in takeover mode, the node will panic with the message ''Permanent errors on all HA mailbox disks''.This is because the node will lose the HA state information and the panic dump files of the partner node, and will not be able to communicate with the partner node or perform a giveback operation3
Therefore, if the motherboard of Node-01 is being replaced, and a takeover was initiated from Node-02, and Node-02 panics showing the string ''Permanent errors on all HA mailbox disks'', the most likely cause is that the mailbox destroy local command was executed on Node-02 while in maintenance mode.This is a serious error that can result in data loss and system downtime4
1: ONTAP 9 - High-Availability Configuration Guide - The Open Group2: ONTAP 9 - Commands: Manual Page Reference - The Open Group3: How to troubleshoot a ''Permanent errors on all HA mailbox disks'' panic - NetApp Knowledge Base4: One node PANIC : Permanent errors on all HA mailbox disks - NetApp Knowledge Base
A 2-node cluster hosts only NAS data UFs. All nodes lose access to the cluster network.
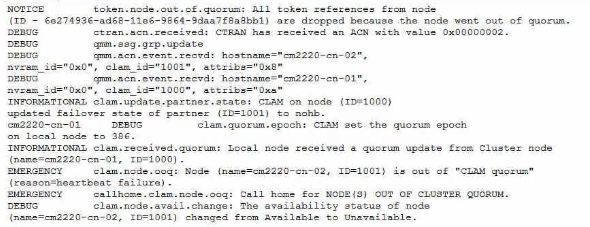
Referring to the exhibit, which statement is correct?
The two throughput elements that are controlled by host applications are operation size and concurrency. Operation size refers to the amount of data that is transferred in a single I/O request, and concurrency refers to the number of I/O requests that are issued simultaneously. Both of these factors affect the throughput of a host application, as they determine how much data can be sent or received within a given time period.Larger operation sizes and higher concurrency can increase the throughput, but they may also increase the latency and resource consumption12.Reference:1: NetApp Performance Analysis on Data ONTAP - Chapter 3: Host-Side Performance2: NetApp Performance Analysis on Data ONTAP - Chapter 4: Storage System Performance
You are troubleshooting a CIFS connection issue that is reported by some users. You decide to collect a packet trace.
In this scenario, after you generate the packet trace, where do you find the trace file?
According to the NetApp Knowledge Base, packet traces are stored in the /etc/log/packet_traces directory of the node hosting the LIF. This applies to ONTAP 9.10 and above systems. For ONTAP 9.2 to 9.9 systems, the procedure to capture packet traces is similar, but the command syntax is slightly different. For ONTAP pre-9.2 systems, the procedure is different and requires the use of the tcpdump command.Reference=How to capture packet traces on ONTAP 9.10+ systems,How to capture packet traces (tcpdump) on ONTAP 9.2 to 9.9 systems,How to capture packet traces in ONTAP pre-9.2
60 questions covering all exam domains, starting from $20
Exam domains verified against: Official NetApp NS0-593 exam guide, last checked September 2026.
Learn tools for support and troubleshooting including how to manage clusters and handle data replication issues. Focus on understanding ONTAP structure, troubleshooting methods, and how to respond to panic events.
Sample question from this domain above: Q1
Study hardware troubleshooting techniques and SP or BMC issues in Fibre Channel environments. Understand cluster interconnect infrastructure and MetroCluster configurations for high availability and disaster recovery.
Sample question from this domain above: Q4
Master ONTAP NAS and SAN configurations for different workload types. Learn S3 server setup and management for object storage use cases within ONTAP environments.
Grasp core ONTAP performance concepts and metrics that affect storage operations. Develop skills in troubleshooting performance issues and optimizing system responsiveness.
Understand how ONTAP delivers software-defined storage capabilities across on-premises, hybrid, and cloud environments. Learn the architectural benefits and deployment options.
Sample question from this domain above: Q5
Common questions about the exam itself

