Key details for this exam, checked against the published exam outline
Each question shows the correct answer and an explanation of why it is right
You have an Azure event hub. Each event contains the following fields:
BikepointID
Street
Neighbourhood
Latitude
Longitude
No_Bikes
No_Empty_Docks
You need to ingest the events. The solution must only retain events that have a Neighbourhood value of Chelsea, and then store the retained events in a Fabric lakehouse.
What should you use?
An eventstream is the best solution for ingesting data from Azure Event Hub into Fabric, while applying filtering logic such as retaining only the events that have a Neighbourhood value of 'Chelsea.' Eventstreams in Microsoft Fabric are designed for handling real-time data streams and can apply transformation logic directly on incoming events. In this case, the eventstream can filter events based on the Neighbourhood field before storing the retained events in a Fabric lakehouse.
Eventstreams are well-suited for stream processing, such as this case where you need to filter out only specific data (events with a Neighbourhood of 'Chelsea') before storing it in the lakehouse.
You have a Fabric workspace named Workspace1 that contains an Apache Spark job definition named Job1.
You have an Azure SQL database named Source1 that has public internet access disabled.
You need to ensure that Job1 can access the data in Source1.
What should you create?
To allow Job1 in Workspace1 to access an Azure SQL database (Source1) with public internet access disabled, you need to create a managed private endpoint. A managed private endpoint is a secure, private connection that enables services like Fabric (or other Azure services) to access resources such as databases, storage accounts, or other services within a virtual network (VNet) without requiring public internet access. This approach maintains the security and integrity of your data while enabling access to the Azure SQL database.
You have a Fabric workspace named Workspace1 that contains a lakehouse named Lakehouse1. Lakehouse1 contains the following tables:
Orders
Customer
Employee
The Employee table contains Personally Identifiable Information (PII).
A data engineer is building a workflow that requires writing data to the Customer table, however, the user does NOT have the elevated permissions required to view the contents of the Employee table.
You need to ensure that the data engineer can write data to the Customer table without reading data from the Employee table.
Which three actions should you perform? Each correct answer presents part of the solution.
NOTE: Each correct selection is worth one point.
To meet the requirements of ensuring that the data engineer can write data to the Customer table without reading data from the Employee table (which contains Personally Identifiable Information, or PII), you can implement the following steps:
Share Lakehouse1 with the data engineer.
By sharing Lakehouse1 with the data engineer, you provide the necessary access to the data within the lakehouse. However, this access should be controlled through roles and permissions, which will allow writing to the Customer table but prevent reading from the Employee table.
Assign the data engineer the Contributor role for Workspace1.
Assigning the Contributor role for Workspace1 grants the data engineer the ability to perform actions such as writing to tables (e.g., the Customer table) within the workspace. This role typically allows users to modify and manage data without necessarily granting them access to view all data (e.g., PII data in the Employee table).
Migrate the Employee table from Lakehouse1 to Lakehouse2.
To prevent the data engineer from accessing the Employee table (which contains PII), you can migrate the Employee table to a separate lakehouse (Lakehouse2) or workspace (Workspace2). This separation of sensitive data ensures that the data engineer's access is restricted to the Customer table in Lakehouse1, while the Employee table can be managed separately and protected under different access controls.
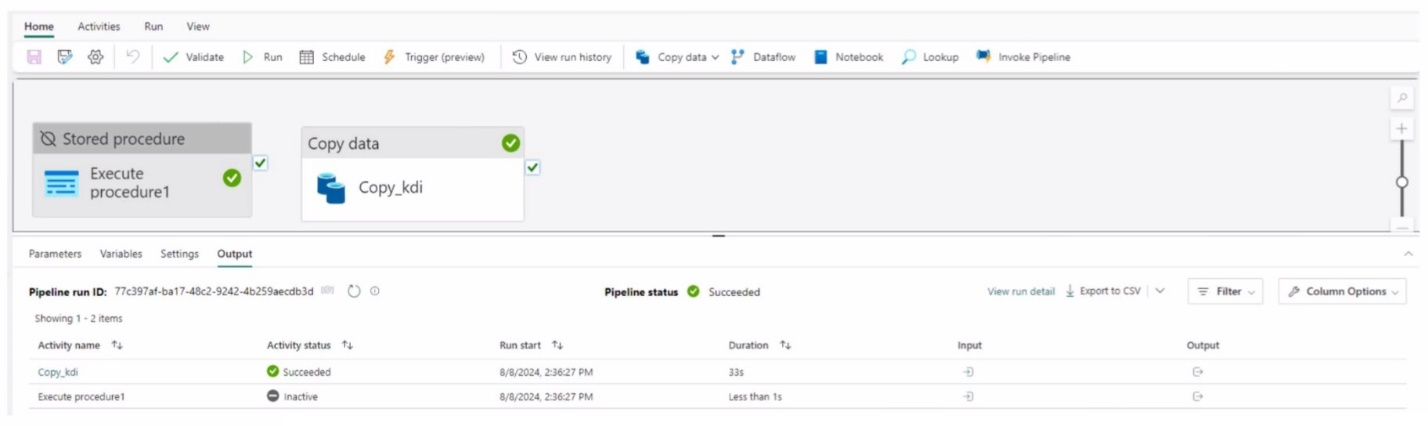
You have a Fabric workspace that contains a data pipeline named Pipeline! as shown in the exhibit.
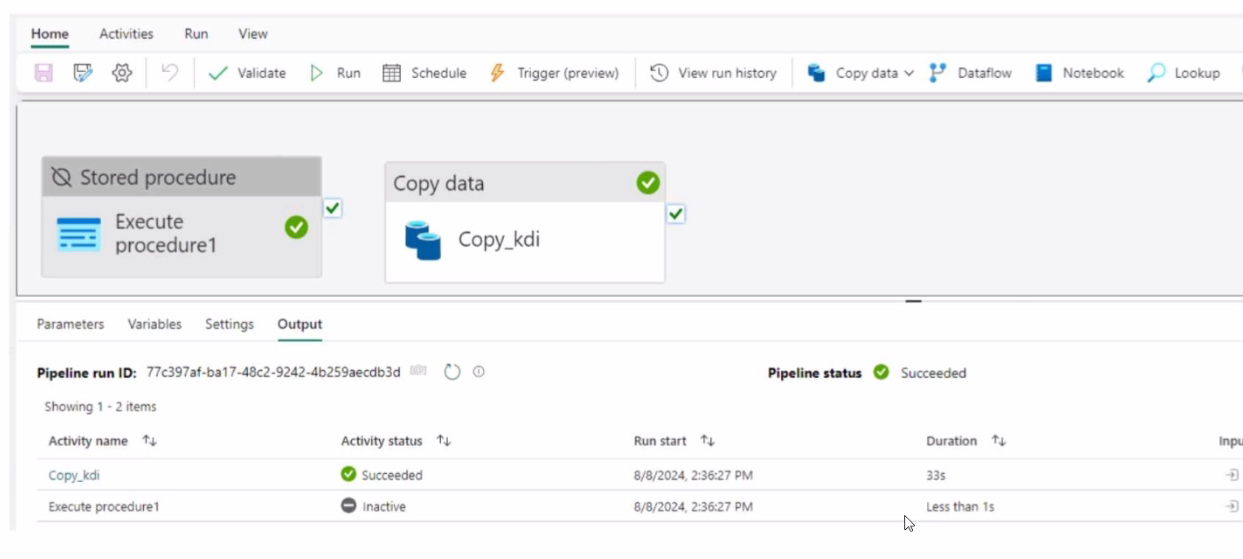
Exhibit.
You have a Fabric workspace that contains a write-intensive warehouse named DW1. DW1 stores staging tables that are used to load a dimensional model. The tables are often read once, dropped, and then recreated to process new data.
You need to minimize the load time of DW1.
What should you do?
You have a Fabric workspace that contains a takehouse and a semantic model named Model1.
You use a notebook named Notebook1 to ingest and transform data from an external data source.
You need to execute Notebook1 as part of a data pipeline named Pipeline1. The process must meet the following requirements:
* Run daily at 07:00 AM UTC.
* Attempt to retry Notebook1 twice if the notebook fails.
* After Notebook1 executes successfully, refresh Model1.
Which three actions should you perform? Each correct answer presents part of the solution. NOTE: Each correct selection is worth one point.
You are developing a data engineering solution in Fabric by using Apache Spark.
You need to monitor the performance of Spark workloads the solution must meet the following requirements
* Provide comprehensive information about the performance of the data engineering workloads.
* Identify stages and tasks that run slowly.
* Minimize administrative effort
What should you use?
To monitor Spark workload performance with comprehensive information, identify slow stages and tasks, and minimize administrative effort, you should use the Spark History Server or the built-in Spark application UI available in Fabric. These tools provide detailed stage and task-level performance metrics, identify bottlenecks, and show execution timelines without requiring additional setup. They are part of the standard Spark runtime and provide all necessary performance insights for data engineering workloads.
Exam domains verified against: Official Microsoft DP-700 exam guide, last checked October 2026.
Configure workspace settings and lifecycle management to establish proper governance foundations. Implement security controls and orchestrate processes to ensure data flows safely through your Fabric environment.
Design loading patterns and build batch pipelines to move data reliably at scale. Work with streaming sources and transformation logic to process continuous data flows using SQL, PySpark, or KQL.
Track Fabric item performance and identify bottlenecks to maintain solution health. Resolve runtime errors and tune queries and resource allocation to keep the platform running efficiently.
Common questions about the exam itself

