Key details for this exam, checked against the published exam outline
Each question shows the correct answer and an explanation of why it is right
What should you use to implement calculation groups for the Research division semantic models?
Unable to provide explanation - the question lacks the necessary options and context. While calculation groups are a feature in Tabular models, the specific tools or methods available for implementing them in the Research division's semantic models are not listed in the question.
You have a Fabric workspace named Workspace1 that contains a data flow named Dataflow1. Dataflow1 contains a query that returns the data shown in the following exhibit.
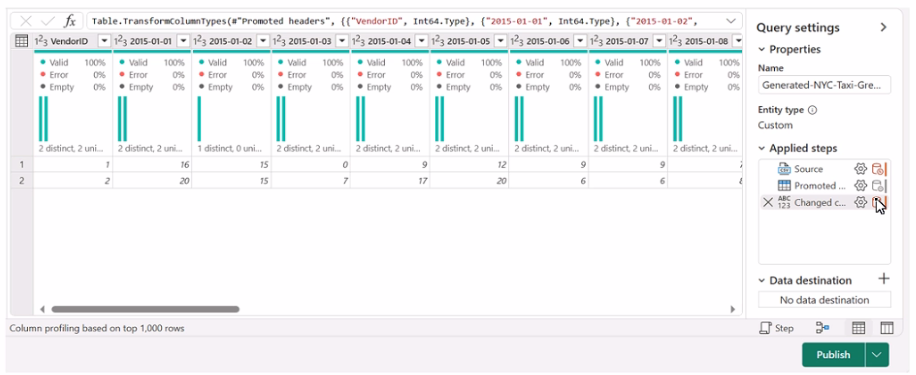
You need to transform the date columns into attribute-value pairs, where columns become rows.
You select the VendorlD column.
Which transformation should you select from the context menu of the VendorlD column?
The transformation you should select from the context menu of the VendorID column to transform the date columns into attribute-value pairs, where columns become rows, is Unpivot columns (B). This transformation will turn the selected columns into rows with two new columns, one for the attribute (the original column names) and one for the value (the data from the cells). Reference = Techniques for unpivoting columns are covered in the Power Query documentation, which explains how to use the transformation in data modeling.
You have a Fabric tenant tha1 contains a takehouse named Lakehouse1. Lakehouse1 contains a Delta table named Customer.
When you query Customer, you discover that the query is slow to execute. You suspect that maintenance was NOT performed on the table.
You need to identify whether maintenance tasks were performed on Customer.
Solution: You run the following Spark SQL statement:
REFRESH TABLE customer
Does this meet the goal?
No, the REFRESH TABLE statement does not provide information on whether maintenance tasks were performed. It only updates the metadata of a table to reflect any changes on the data files. Reference = The use and effects of the REFRESH TABLE command are explained in the Spark SQL documentation.
You have a Fabric warehouse that contains a table named Staging.Sales. Staging.Sales contains the following columns.
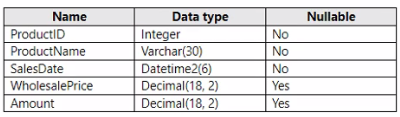
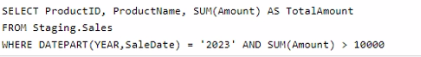
You need to write a T-SQL query that will return data for the year 2023 that displays ProductID and ProductName arxl has a summarized Amount that is higher than 10,000. Which query should you use?
A)
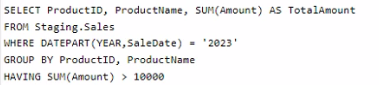
B)
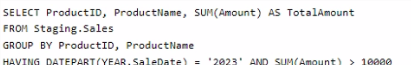
C)
D)
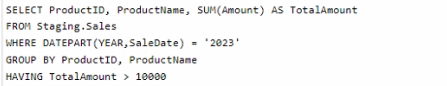
The correct query to use in order to return data for the year 2023 that displays ProductID, ProductName, and has a summarized Amount greater than 10,000 is Option B. The reason is that it uses the GROUP BY clause to organize the data by ProductID and ProductName and then filters the result using the HAVING clause to only include groups where the sum of Amount is greater than 10,000. Additionally, the DATEPART(YEAR, SaleDate) = '2023' part of the HAVING clause ensures that only records from the year 2023 are included. Reference = For more information, please visit the official documentation on T-SQL queries and the GROUP BY clause at T-SQL GROUP BY.
You have a Microsoft Power Bl semantic model that contains a single table named Orders. Orders contains the following columns:
* Product Name
* Order Date
* Quantity
You have a Power Bl report that contains a page named Inventory. Inventory contains a slicer for the Product Name column and a clustered column chart that shows Quantity by Order Date.
You need to ensure that users can select whether to display Quantity by Product Name or Quantity by Order Date in the chart. The solution must minimize development effort.
What should you create?
To allow users to select whether to display Quantity by Product Name or Quantity by Order Date with minimal development effort, you should create a bookmark. Bookmarks capture the current state of a report page (including which fields are in the visualization) and can be toggled via buttons. This is the most straightforward solution that requires no additional measures or complex DAX logic. Alternatively, a field parameter could be used, but bookmarks offer the most minimal development effort for this scenario.
You have a Fabric tenant that contains a lakehouse named lakehouse1. Lakehouse1 contains a table named Table1.
You are creating a new data pipeline.
You plan to copy external data to Table1. The schema of the external data changes regularly.
You need the copy operation to meet the following requirements:
* Replace Table1 with the schema of the external data.
* Replace all the data in Table1 with the rows in the external data.
You add a Copy data activity to the pipeline. What should you do for the Copy data activity?
For the Copy data activity, from the Destination tab, setting Table action to Overwrite (B) will ensure that Table1 is replaced with the schema and rows of the external data, meeting the requirements of replacing both the schema and data of the destination table. Reference = Information about Copy data activity and table actions in Azure Data Factory, which can be applied to data pipelines in Fabric, is available in the Azure Data Factory documentation.
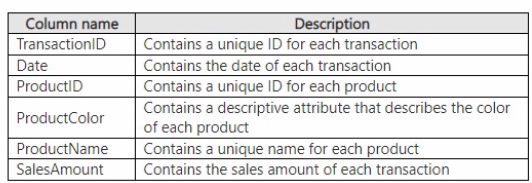
You have a Fabric workspace named Workspacel that contains a lakehouse named Lakehousel. Lakehousel contains a table named Tablel. Table 1 contains the following data.
You need to perform the following actions:
* Load the data from Table! into a star schema.
* Create a product dimension table named DimProduct and a fact table named FactSales.
Which three columns should you include in DimProduct?
For a star schema with DimProduct (product dimension) and FactSales (fact table), DimProduct should include:
These three columns form the core of a product dimension table:
The FactSales table would contain ProductID as a foreign key along with sales metrics like OrderQty and SalesOrderID.
Exam domains verified against: Official Microsoft DP-600 exam guide, last checked October 2026.
Create objects in a lakehouse or warehouse and copy data efficiently. Transform data through dataflows, Spark notebooks, and Data Factory pipelines. Optimize query performance and organize data for analytical readiness.
Sample question from this domain above: Q3
Design and construct semantic models that structure data meaningfully for analysis. Build DAX calculations and establish table relationships. Optimize large-scale semantic models to enhance efficiency and usability in enterprise environments.
Implement security through row-level security and object-level security alongside Purview governance. Monitor solution health and handle capacity management. Maintain the analytics development lifecycle through proper deployment and version control.
Common questions about the exam itself

