
Free Microsoft DP-203 Exam Practice Questions & Explanations
Prepared & Reviewed by the ValidExamDumps Editorial Team
At ValidExamDumps, we consistently monitor updates to the Microsoft DP-203 exam questions by Microsoft. Whenever our team identifies changes in the exam questions, objectives, focus areas or requirements, We immediately update our exam questions for both PDF and online practice exams. This commitment ensures our customers always have access to the most current and accurate questions. By preparing with these up to date and 100% exam domain coverage questions, our customers can successfully pass the Microsoft Data Engineering on Microsoft Azure exam on their first attempt without needing additional materials or study guides.
Other certification materials providers often include outdated or removed questions by Microsoft in their DP-203 exam. These outdated questions lead to customers failing their Microsoft Data Engineering on Microsoft Azure exam. In contrast, we ensure our questions bank includes only precise and up-to-date questions. Our main priority is your success in the Microsoft DP-203 exam, not profiting from selling obsolete exam questions in PDF or Online Practice Test.
You have an Azure Synapse Analytics Apache Spark pool named Pool1.
You plan to load JSON files from an Azure Data Lake Storage Gen2 container into the tables in Pool1. The structure and data types vary by file.
You need to load the files into the tables. The solution must maintain the source data types.
What should you do?
Serverless SQL pool can automatically synchronize metadata from Apache Spark. A serverless SQL pool database will be created for each database existing in serverless Apache Spark pools.
Serverless SQL pool enables you to query data in your data lake. It offers a T-SQL query surface area that accommodates semi-structured and unstructured data queries.
To support a smooth experience for in place querying of data that's located in Azure Storage files, serverless SQL pool uses the OPENROWSET function with additional capabilities.
The easiest way to see to the content of your JSON file is to provide the file URL to the OPENROWSET function, specify csv FORMAT.
https://docs.microsoft.com/en-us/azure/synapse-analytics/sql/query-json-files
https://docs.microsoft.com/en-us/azure/synapse-analytics/sql/query-data-storage
You are designing a statistical analysis solution that will use custom proprietary1 Python functions on near real-time data from Azure Event Hubs.
You need to recommend which Azure service to use to perform the statistical analysis. The solution must minimize latency.
What should you recommend?
You have an Azure subscription that contains an Azure Synapse Analytics dedicated SQL pool named Pool1. Pool1 receives new data once every 24 hours.
You have the following function.
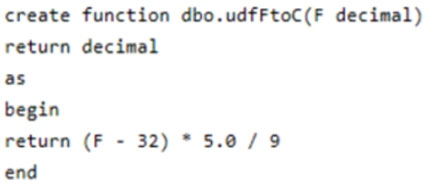
You have the following query.

The query is executed once every 15 minutes and the @parameter value is set to the current date.
You need to minimize the time it takes for the query to return results.
Which two actions should you perform? Each correct answer presents part of the solution.
NOTE: Each correct selection is worth one point.
You plan to perform batch processing in Azure Databricks once daily.
Which type of Databricks cluster should you use?
Azure Databricks has two types of clusters: interactive and automated. You use interactive clusters to analyze data collaboratively with interactive notebooks. You use automated clusters to run fast and robust automated jobs.
Example: Scheduled batch workloads (data engineers running ETL jobs)
This scenario involves running batch job JARs and notebooks on a regular cadence through the Databricks platform.
The suggested best practice is to launch a new cluster for each run of critical jobs. This helps avoid any issues (failures, missing SLA, and so on) due to an existing workload (noisy neighbor) on a shared cluster.
You plan to create an Azure Data Factory pipeline that will include a mapping data flow.
You have JSON data containing objects that have nested arrays.
You need to transform the JSON-formatted data into a tabular dataset. The dataset must have one tow for each item in the arrays.
Which transformation method should you use in the mapping data flow?
Use the flatten transformation to take array values inside hierarchical structures such as JSON and unroll them into individual rows. This process is known as denormalization.
https://docs.microsoft.com/en-us/azure/data-factory/data-flow-flatten