
Free Microsoft DP-100 Exam Practice Questions & Explanations
Prepared & Reviewed by the ValidExamDumps Editorial Team
At ValidExamDumps, we consistently monitor updates to the Microsoft DP-100 exam questions by Microsoft. Whenever our team identifies changes in the exam questions, objectives, focus areas or requirements, We immediately update our exam questions for both PDF and online practice exams. This commitment ensures our customers always have access to the most current and accurate questions. By preparing with these up to date and 100% exam domain coverage questions, our customers can successfully pass the Microsoft Designing and Implementing a Data Science Solution on Azure exam on their first attempt without needing additional materials or study guides.
Other certification materials providers often include outdated or removed questions by Microsoft in their DP-100 exam. These outdated questions lead to customers failing their Microsoft Designing and Implementing a Data Science Solution on Azure exam. In contrast, we ensure our questions bank includes only precise and up-to-date questions. Our main priority is your success in the Microsoft DP-100 exam, not profiting from selling obsolete exam questions in PDF or Online Practice Test.
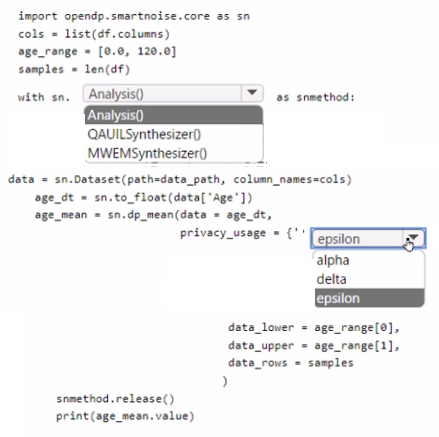
You load data from a notebook in an Azure Machine Learning workspace into a pandas dataframe named df. The data contains 10.000 patient records. Each record includes the Age property for the corresponding patient.
You must identify the mean age value from the differentially private data generated by SmartNoise SDK.
You need to complete the Python code that will generate the mean age value from the differentially private data.
Which code segments should you use? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.
Correct answer area highlighted in green
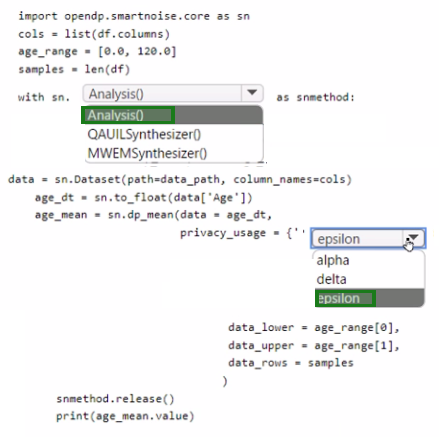
To generate the mean age value from differentially private data using SmartNoise SDK, you would need to complete code segments that include:
<ul><li>Import SmartNoise analysis and session classes: <code>from opendp.smartnoise.sql import PrivateReader</code> or <code>from opendp.smartnoise.analysis import Analysis</code></li><li>Create a session or reader with differential privacy budgets (epsilon and delta values)</li><li>Execute a query or analysis that calculates mean with differential privacy applied</li><li>Access the result and privacy metadata</li></ul>A typical code pattern would involve:
<ol><li>Creating a PrivateReader or Analysis object</li><li>Specifying the DataFrame, column ('Age'), and privacy parameters</li><li>Calling the mean() method with privacy budgets</li><li>Extracting the differentially private result</li></ol>The specific code segments to select depend on the answer options shown in the actual question.
You are performing a filter based feature selection for a dataset 10 build a multi class classifies by using Azure Machine Learning Studio.
The dataset contains categorical features that are highly correlated to the output label column.
You need to select the appropriate feature scoring statistical method to identify the key predictors. Which method should you use?
Pearson's correlation statistic, or Pearson's correlation coefficient, is also known in statistical models as the r value. For any two variables, it returns a value that indicates the strength of the correlation
Pearson's correlation coefficient is the test statistics that measures the statistical relationship, or association, between two continuous variables. It is known as the best method of measuring the association between variables of interest because it is based on the method of covariance. It gives information about the magnitude of the association, or correlation, as well as the direction of the relationship.
https://www.statisticssolutions.com/pearsons-correlation-coefficient/
You are creating a machine learning model.
You need to identify outliers in the data.
Which two visualizations can you use? Each correct answer presents a complete solution.
NOTE: Each correct selection is worth one point.
NOTE: Each correct selection is worth one point.
The box-plot algorithm can be used to display outliers.
One other way to quickly identify Outliers visually is to create scatter plots.
https://blogs.msdn.microsoft.com/azuredev/2017/05/27/data-cleansing-tools-in-azure-machine-learning/
Note: This question is part of a series of questions that present the same scenario. Each question in the series contains a unique solution that might meet the stated goals. Some question sets might have more than one correct solution, while others might not have a correct solution.
After you answer a question in this section, you will NOT be able to return to it. As a result, these questions will not appear in the review screen.
You use Azure Machine Learning designer to load the following datasets into an experiment:

You need to create a dataset that has the same columns and header row as the input datasets and contains all rows from both input datasets.
Solution: Use the Execute Python Script module.
Does the solution meet the goal?
You are solving a classification task.
You must evaluate your model on a limited data sample by using k-fold cross-validation. You start by configuring a k parameter as the number of splits.
You need to configure the k parameter for the cross-validation.
Which value should you use?
Leave One Out (LOO) cross-validation
Setting K = n (the number of observations) yields n-fold and is called leave-one out cross-validation (LOO), a special case of the K-fold approach.
LOO CV is sometimes useful but typically doesn't shake up the data enough. The estimates from each fold are highly correlated and hence their average can have high variance.
This is why the usual choice is K=5 or 10. It provides a good compromise for the bias-variance tradeoff.
You are creating a machine learning model. You have a dataset that contains null rows.
You need to use the Clean Missing Data module in Azure Machine Learning Studio to identify and resolve the null and missing data in the dataset.
Which parameter should you use?
Remove entire row: Completely removes any row in the dataset that has one or more missing values. This is useful if the missing value can be considered randomly missing.
https://docs.microsoft.com/en-us/azure/machine-learning/studio-module-reference/clean-missing-data
Note: This question is part of a series of questions that present the same scenario. Each question in the series contains a unique solution that might meet the stated goals. Some question sets might have more than one correct solution, while others might not have a correct solution.
After you answer a question in this section, you will NOT be able to return to it. As a result, these questions will not appear in the review screen.
You train and register a machine learning model.
You plan to deploy the model as a real-time web service. Applications must use key-based authentication to use the model.
You need to deploy the web service.
Solution:
Create an AksWebservice instance.
Set the value of the auth_enabled property to False.
Set the value of the token_auth_enabled property to True.
Deploy the model to the service.
Does the solution meet the goal?
Instead use only auth_enabled = TRUE
Note: Key-based authentication.
Web services deployed on AKS have key-based auth enabled by default. ACI-deployed services have key-based auth disabled by default, but you can enable it by setting auth_enabled = TRUE when creating the ACI web service. The following is an example of creating an ACI deployment configuration with key-based auth enabled.
deployment_config <- aci_webservice_deployment_config(cpu_cores = 1,
memory_gb = 1,
auth_enabled = TRUE)
https://azure.github.io/azureml-sdk-for-r/articles/deploying-models.html
You manage an Azure Machine Learning workspace. You have an environment for training jobs which uses an existing Docker image. A new version of the Docker image is available.
You need to use the latest version of the Docker image for the environment configuration by using the Azure Machine Learning SDK v2-What should you do?
To use the latest version of a Docker image with Azure ML SDK v2:
<ul><li><strong>Remove the current version</strong> - Delete or don't reuse the environment that references the old Docker image version</li><li><strong>Create a new environment</strong> - Create a fresh environment configuration that explicitly specifies the new/latest Docker image tag or reference</li></ul>When updating to a new Docker image version using SDK v2:
<ul><li>You cannot modify an existing environment definition in-place</li><li>You must create a new Environment object with the updated image reference</li><li>Register this new environment in your workspace</li><li>Use the new environment in your training job configuration</li></ul>This approach ensures a clean separation between versions and guarantees that the latest image version is properly downloaded and used for training jobs.