
iSQI CT-AI Practice Exam Questions & Answers
iSQI CT-AI Exam Details
Key details for this exam, checked against the published exam outline
- Exam Code
- CT-AI
- Full Name
- ISTQB Certified Tester AI Testing (CT-AI)
- Issuing Body
- International Software Testing Qualifications Board (ISTQB)
- Question Format (Our Bank)
- Multiple Choice
- Eligibility
- ISTQB Certified Tester Foundation Level (CTFL) required
- Full Question Set
- 120 questions Get All Questions
Free CT-AI Practice Questions
Each question shows the correct answer and an explanation of why it is right
Question 1 Domain 4 ML: Data
Which statement about testing levels for AI-based systems is correct?
Choose ONE option (1 out of 4)
Section4.3 -- Test Levels for AI Systemsclearly defines ML model testing as the level at which testers evaluate whether an ML model fulfills itsfunctional performance criteria, including accuracy, precision, recall, F1, robustness, stability, and fairness. Therefore, Option C is the correct and syllabus-aligned statement.
Option A is incorrect because input data testing focuses onvalidity and correctness of data entering the model, not interactions with all system components. Option B is incorrect: acceptance testing in the syllabus focuses primarily onbusiness and stakeholder requirements, not specifically explainability. Explainability testing may occur at multiple levels depending on context. Option D is also incorrect because API testing belongs tointegration testing, not system testing, even when AI is consumed as a service.
Thus,Option Cis the only statement that precisely matches syllabus definitions.
Question 2 Domain 8 Testing AI-Specific Quality Characteristic
Upon testing a model used to detect rotten tomatoes, the following data was observed by the test engineer, based on certain number of tomato images.
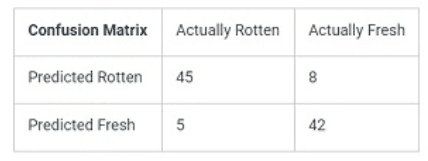
For this confusion matrix which combinations of values of accuracy, recall, and specificity respectively is CORRECT?
SELECT ONE OPTION
To calculate the accuracy, recall, and specificity from the confusion matrix provided, we use the following formulas:
Confusion Matrix:
Actually Rotten: 45 (True Positive), 8 (False Positive)
Actually Fresh: 5 (False Negative), 42 (True Negative)
Accuracy:
Accuracy is the proportion of true results (both true positives and true negatives) in the total population.
Formula: Accuracy=TP+TNTP+TN+FP+FN\text{Accuracy} = \frac{TP + TN}{TP + TN + FP + FN}Accuracy=TP+TN+FP+FNTP+TN
Calculation: Accuracy=45+4245+42+8+5=87100=0.87\text{Accuracy} = \frac{45 + 42}{45 + 42 + 8 + 5} = \frac{87}{100} = 0.87Accuracy=45+42+8+545+42=10087=0.87
Recall (Sensitivity):
Recall is the proportion of true positive results in the total actual positives.
Formula: Recall=TPTP+FN\text{Recall} = \frac{TP}{TP + FN}Recall=TP+FNTP
Calculation: Recall=4545+5=4550=0.9\text{Recall} = \frac{45}{45 + 5} = \frac{45}{50} = 0.9Recall=45+545=5045=0.9
Specificity:
Specificity is the proportion of true negative results in the total actual negatives.
Formula: Specificity=TNTN+FP\text{Specificity} = \frac{TN}{TN + FP}Specificity=TN+FPTN
Calculation: Specificity=4242+8=4250=0.84\text{Specificity} = \frac{42}{42 + 8} = \frac{42}{50} = 0.84Specificity=42+842=5042=0.84
Therefore, the correct combinations of accuracy, recall, and specificity are 0.87, 0.9, and 0.84 respectively.
References:
ISTQB CT-AI Syllabus, Section 5.1, Confusion Matrix, provides detailed formulas and explanations for calculating various metrics including accuracy, recall, and specificity.
'ML Functional Performance Metrics' (ISTQB CT-AI Syllabus, Section 5).
Question 3 Domain 1 Introduction to AI
Which machine learning approach is most suitable for predicting customer purchase probability?
Choose ONE option (1 out of 4)
The ISTQB CT-AI syllabus explains in Section1.6 -- Machine Learning Approachesthatsupervised learningis appropriate when labeled data exists and the goal is to predict an output based on known historical examples. Predicting a customer'spurchase probabilityis aclassificationtask when the output corresponds to discrete categories such as''likely to purchase''vs.''not likely to purchase.''The syllabus gives similar examples in describing classification as the process of assigning instances to predefined classes based on learned patterns in labeled data. Because the retail company wants to determine whether a customer will make a purchase based on marketing actions, classification is the most appropriate choice .
Option A (regression) predicts continuous numeric values and is less suitable because the task centers oncategorical likelihood, not estimating exact monetary values. Option C (unsupervised learning) is used when labels are not available---here, the company has labeled purchase histories. Option D (reinforcement learning) requires an interactive environment with reward-driven behavior, which is not applicable to this scenario.
Thus,supervised learning (classification)is the most suitable approach according to the syllabus.
Get the complete CT-AI question set
$20$40
Question 4 Domain 4 ML: Data
Written requirements are given in text documents, which ONE of the following options is the BEST way to generate test cases from these requirements?
SELECT ONE OPTION
When written requirements are given in text documents, the best way to generate test cases is by using Natural Language Processing (NLP). Here's why:
Natural Language Processing (NLP): NLP can analyze and understand human language. It can be used to process textual requirements to extract relevant information and generate test cases. This method is efficient in handling large volumes of textual data and identifying key elements necessary for testing.
Why Not Other Options:
Analyzing source code for generating test cases: This is more suitable for white-box testing where the code is available, but it doesn't apply to text-based requirements.
Machine learning on logs of execution: This approach is used for dynamic analysis based on system behavior during execution rather than static textual requirements.
GUI analysis by computer vision: This is used for testing graphical user interfaces and is not applicable to text-based requirements.
References:This aligns with the methodology discussed in the syllabus under the section on using AI for generating test cases from textual requirements.
Question 5 Domain 4 ML: Data
Which challenge to testing self-learning systems puts you at risk of a data attack?
Choose ONE option (1 out of 4)
The ISTQB CT-AI syllabus describes thatself-learning systems continuously adjust their behaviorduring operation as new data arrives. Section4.1 -- Challenges of Testing AI-Based Systemshighlights that such systems are vulnerable todata attacks, particularly through adversarial inputs, poisoning, or malicious drift. The risk arises because unexpected changes in the input distribution may alter the learned model in harmful ways. OptionD -- Unexpected changescorresponds directly to this syllabus-defined risk.
Option A refers to system specification issues but does not relate to data attacks. Option B discusses environment complexity, which makes testing difficult but is not tied to adversarial threats. Option C (insufficient testing time) affects quality but does not specifically increase vulnerability to malicious data manipulation.
Unexpected changes---including data drift, poisoned samples, or maliciously constructed training data---pose the greatest risk. When a self-learning system adapts to altered data patterns, it may unknowingly learn incorrect associations, causing model degradation or manipulation. Therefore,Option Dcorrectly identifies the challenge that increases exposure to data attacks.
Question 6 Domain 2 Quality Characteristics for AI-Based Systems
Which performance metric is BEST suited to assess the quality of trained models detecting fraudulent credit card transactions?
Choose ONE option (1 out of 4)
The ISTQB CT-AI syllabus explains in Section3.2 -- Functional Performance Criteria of ML Modelsthat accuracy becomes unreliable whenclass imbalanceexists. In fraud detection, more than 99% of transactions are non-fraudulent, meaning the dataset is extremely imbalanced. Because accuracy counts all correct non-fraudulent classifications, it will appear artificially high, even if the fraud detection performance is poor. Therefore, accuracy is not suitable for evaluating fraud detection systems.
The syllabus further explains thatsensitivity (recall)captures the proportion of correctly identified fraudulent cases. This metric is important, as missing fraudulent events can cause high financial loss. However, the client also stresses thatlegitimate transactions must be correctly identified, meaningfalse positives must be minimizedto maintain customer satisfaction.
TheF1 score, defined as the harmonic mean ofprecision and recall, balances both:
Precision protects legitimate customers by minimizing false alarms.
Recall ensures fraudulent transactions are detected.
Section 3.2 emphasizes that when both false positives and false negatives have significant consequences, and the data is highly imbalanced,F1 is the most appropriate metricbecause it reflects the combined importance of detecting fraud while avoiding unnecessary alerts. Thus,Option Cis the correct choice.
Question 7 Domain 3 Machine Learning ML
Which of the following is an example of overfitting?
The syllabus defines overfitting as:
''Overfitting is when the ML model learns the training data so well that it is unable to generalize to accommodate new data.''
This occurs when the model memorizes the training data, including noise, instead of learning the general patterns.
(Reference: ISTQB CT-AI Syllabus v1.0, Section 3.5.1, page 31 of 99)
What the iSQI CT-AI Exam Covers
Exam domains verified against the Official iSQI CT-AI exam guide, last checked October 2026.
Domain 1 Introduction to AI
Covers the definition and impact of AI, the differences between narrow AI, general AI, and super AI, and how standards apply to AI-based systems. Understand the foundational concepts that distinguish different types of artificial intelligence and their relevance to testing practice.
Sample question from this domain above Q3
Domain 2 Quality Characteristics for AI-Based Systems
Addresses the importance of flexibility and adaptability as key attributes of AI systems, and examines how the evolution of AI-based systems affects quality. Learn what makes AI quality different from traditional software quality.
Sample question from this domain above Q6
Domain 3 Machine Learning ML
Covers classification and regression as part of supervised learning, explains the factors involved in selecting ML algorithms, and demonstrates how to recognize underfitting and overfitting. Understand the fundamentals of how machine learning models are built and trained.
Sample question from this domain above Q7
Domain 4 ML: Data
Addresses the challenges of data preparation and testing, demonstrates how to create a machine learning framework, and shows how poor data quality can cause issues in production. Recognize why data quality is as critical as model quality in ML systems.
Domain 5 ML Functional Performance Metrics
Covers measuring the performance of machine learning models using metrics derived from the confusion matrix. Learn to calculate and interpret key performance indicators that tell you whether your model actually works.
Domain 6 Neural Networks and Testing
Describes the structure and function of neural networks, the role of deep neural networks, and coverage measures specific to neural network testing. Understand how neural networks differ from traditional algorithms and why standard test coverage does not apply.
Domain 7 Testing AI-Based Systems Overview
Addresses how system specifications for AI-based systems create testing challenges, explains automation bias and its effects on testing, and covers the unique risks inherent in AI systems. Learn why traditional testing approaches can miss the problems AI systems introduce.
Domain 8 Testing AI-Specific Quality Characteristic
Examines challenges that emerge during testing due to the self-learning capabilities of AI-based systems. Recognize how continuous learning and adaptation change what needs to be tested over the lifetime of a system.
Sample question from this domain above Q2
Domain 9 Methods and Techniques for the Testing of AI-Based Systems:
Explores the benefits of testing machine learning systems using specific methods, and shows how these techniques help reduce attacks and protect against data poisoning. Apply practical testing strategies that address the unique vulnerabilities of AI systems.
Domain 10 Test Environments for AI-Based Systems
Covers the factors that distinguish test environments for AI-based systems from conventional software test environments. Understand what infrastructure, data, and configurations are needed to test AI systems effectively.
Domain 11 Using AI for Testing
Covers classifying the AI technologies that are used to support and automate testing processes. Learn how AI itself can be applied to improve test automation, test case generation, and defect detection.
CT-AI Exam FAQ
Common questions about the exam itself
What background do I need to take the CT-AI exam?
How long is the CT-AI exam?
What score do I need to pass CT-AI?
How long does CT-AI certification stay valid?
What is the hardest part of CT-AI to study?
How much preparation time do I need for CT-AI?
What is the difference between CT-AI and CT-GenAI?
Can I retake the CT-AI exam if I fail?
What job roles is CT-AI meant for?
Is CT-AI version 1.0 still available or do I need to take version 2.0?
Other iSQI Exams
Free practice questions for more iSQI certification exams