Databricks Databricks-Machine-Learning-Professional Practice Exam Questions & Answers

7 Free Questions Last reviewed November 2, 2026 Prepared & Reviewed by the ValidExamDumps Editorial Team

60 Practice Questions (Our Bank)
120 minutes Exam Duration
70% Passing Score
USD 200 Official Exam Fee
Exam Facts

Databricks Databricks-Machine-Learning-Professional Exam Details

Key details for this exam, checked against the published exam outline

Exam Code
Databricks-Machine-Learning-Professional
Full Name
Databricks Certified Machine Learning Professional
Issuing Body
Databricks
Question Format (Our Bank)
Multiple Choice
Delivery
Online proctored
Eligibility
1+ years of hands-on experience performing the machine learning tasks outlined in the exam guide
Validity
2 years
Practice Questions

Free Databricks-Machine-Learning-Professional Practice Questions

Each question shows the correct answer and an explanation of why it is right

VA
ValidExamDumps Editorial Team Every question and its answer is checked by our Databricks-Machine-Learning-Professional exam preparation team, who also write the explanation shown with each one. How we research and review these pages

Question 1 Domain 3 Model Deployment

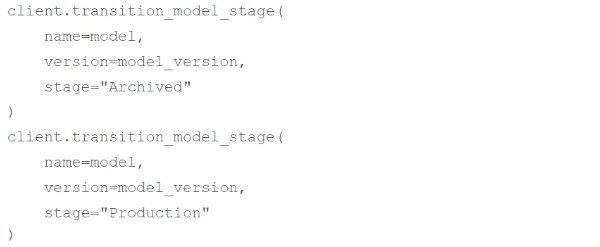
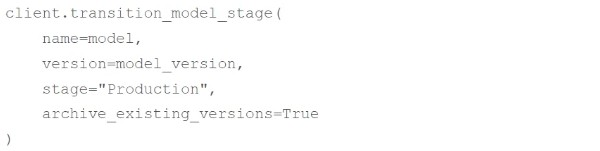
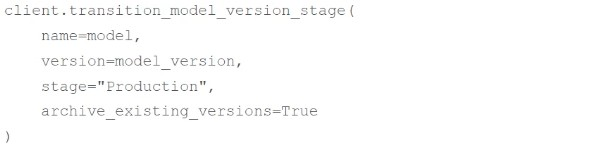
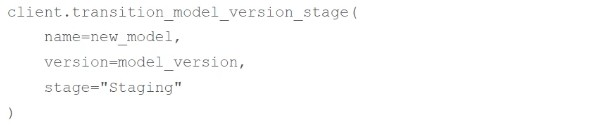
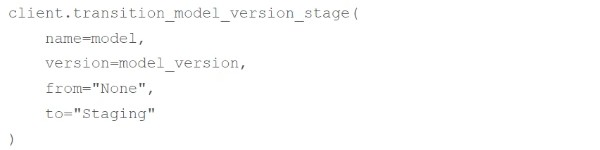
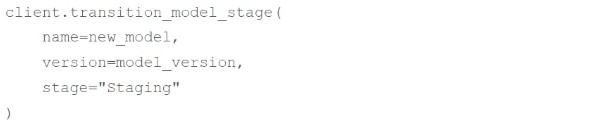
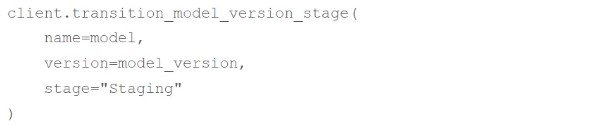
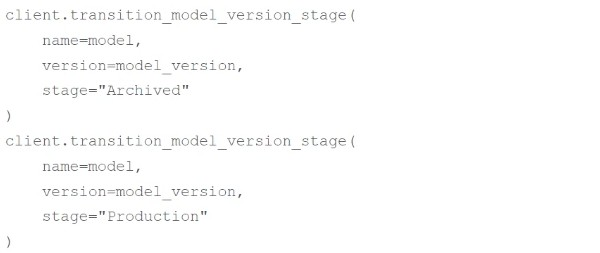
A machine learning engineer wants to move their model version model_version for the MLflow Model Registry model model from the Staging stage to the Production stage using MLflow Client client. At the same time, they would like to archive any model versions that are already in the Production stage.

Which of the following code blocks can they use to accomplish the task?

A)
Question 1 exhibit

B)

Question 1 exhibit

C)

Question 1 exhibit

D)

Question 1 exhibit

Correct Answer C
Explanation To query a model in Production stage from MLflow Model Serving, you need the specific version number. Model URIs in MLflow require the version number because a stage can contain only one version at a time, but the system needs to know exactly which version to serve. Without the version number, the URI cannot uniquely identify the model version to query. This is a core aspect of model deployment and registry management in MLflow.

Question 2 Domain 1 Model Development

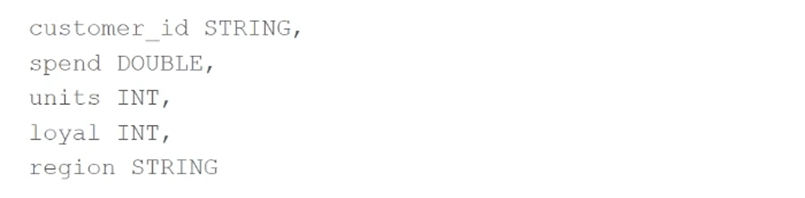
A data scientist has created a Python function compute_features that returns a Spark DataFrame with the following schema:
Question 2 exhibit

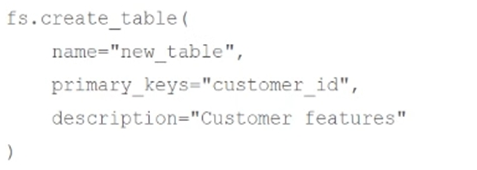
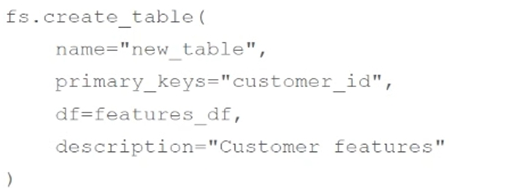
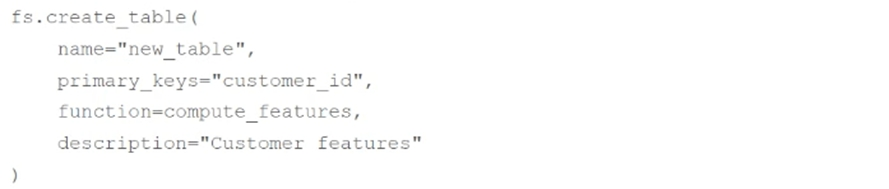
The resulting DataFrame is assigned to the features_df variable. The data scientist wants to create a Feature Store table using features_df.

Which of the following code blocks can they use to create and populate the Feature Store table using the Feature Store Client fs?

A)
Question 2 exhibit

B)

Question 2 exhibit

C)

features_df.write.mode("fs").path("new_table")

D)
Question 2 exhibit

Correct Answer D
Explanation MLflow.log_metric is designed to log single numeric values that track model parameters or performance measurements across runs. The number of trees in a random forest is a parameter that changes across experiments, making it a metric to log. Other options like log_artifact (for files) or log_model (for the entire model) serve different purposes. Using log_metric allows the data scientist to compare and track how the tree count affects model performance.

Question 3 Domain 1 Model Development

In a continuous integration, continuous deployment (CI/CD) process for machine learning pipelines, which of the following events commonly triggers the execution of automated testing?

Correct Answer D
Explanation The correct approach to log a scikit-learn model with MLflow is using mlflow.sklearn.log_model(), not mlflow.spark.track_model(). The function mlflow.sklearn.log_model() is the proper MLflow API for logging scikit-learn models. It handles the serialization and tracking of the model artifact within an active MLflow run. Other incorrect options might use wrong module names or incorrect function signatures that MLflow does not provide.

Get the complete Databricks-Machine-Learning-Professional question set $20$40

Get Full Access

Question 4 Domain 2 MLOps

A data scientist has developed and logged a scikit-learn random forest model model, and then they ended their Spark session and terminated their cluster. After starting a new cluster, they want to review the feature_importances_ of the original model object.

Which of the following lines of code can be used to restore the model object so that feature_importances_ is available?

Correct Answer A
Explanation Data type tests and checks matter for streaming deployments because streaming systems run continuously and must handle data consistently as it arrives. Unlike batch jobs that process data at specific times, streaming deployments need to validate incoming data formats immediately. This validation ensures the model receives properly formatted inputs and can detect schema changes before they cause failures. Autoscaling is a separate operational concern unrelated to data validation requirements.

Question 5 Domain 1 Model Development

Which of the following statements describes streaming with Spark as a model deployment strategy?

Correct Answer E
Explanation The context parameter in MLflow's predict method allows you to specify which version of a registered model should be used for predictions. This enables you to control model behavior based on your application's needs or environment. You might want to use different versions in development versus production, or switch versions based on specific scenarios. The context parameter gives you this flexibility without changing the calling code itself.

Question 6 Domain 2 MLOps

A machine learning engineer needs to deliver predictions of a machine learning model in real-time. However, the feature values needed for computing the predictions are available one week before the query time.

Which of the following is a benefit of using a batch serving deployment in this scenario rather than a real-time serving deployment where predictions are computed at query time?

Correct Answer A
Explanation Label drift occurs when the distribution of the target variable changes over time. This means the output or prediction target you are trying to model shifts, not the input features. If input variable distributions change, that is feature drift instead. Label drift indicates the underlying problem you are solving has shifted, which can cause even previously accurate models to perform poorly because the relationship between features and labels has fundamentally changed.

Question 7 Domain 3 Model Deployment

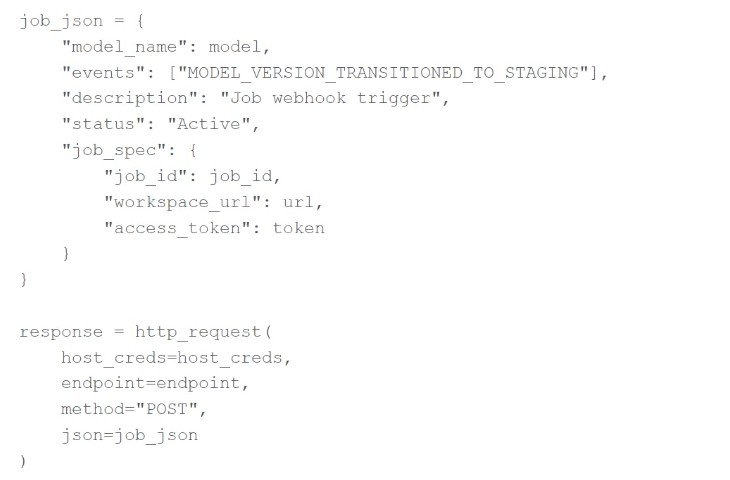
A machine learning engineer has created a webhook with the following code block:
Question 7 exhibit

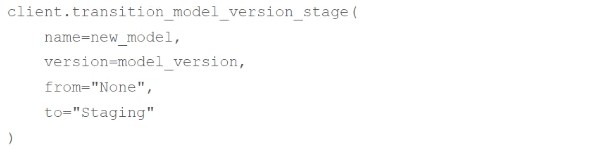
Which of the following code blocks will trigger this webhook to run the associate job?

A)
Question 7 exhibit

B)

Question 7 exhibit

C)

Question 7 exhibit

D)

Question 7 exhibit

E)

Question 7 exhibit

Correct Answer C
Explanation MLflow.register_model requires two arguments: the model URI and the name for the registered model in the MLflow Model Registry. The model_uri variable contains the complete path needed to locate the model artifact, while 'best_model' is the desired registration name. This method specifically registers models to the MLflow Model Registry, which is part of the model deployment process. Other approaches like using run_id directly or specifying the original model name would not register the model with the new name 'best_model' as required.
Study Guide

What the Databricks Databricks-Machine-Learning-Professional Exam Covers

Exam domains verified against the Official Databricks Databricks-Machine-Learning-Professional exam guide, last checked November 2026.

Domain 1 Model Development

44%

Build scalable ML pipelines using SparkML estimators, transformers, and feature engineering techniques. Master hyperparameter tuning with MLlib, Optuna, and Ray, plus advanced MLflow tracking and custom model objects with real-time feature engineering.

Sample questions from this domain above Q2Q3Q5

Domain 2 MLOps

44%

Design model lifecycle architectures, implement unit and integration testing across environments, and automate retraining workflows. Configure Databricks ML assets with DABs, detect data drift using Lakehouse Monitoring, and set up monitoring pipelines with alerting for infrastructure and model performance metrics.

Sample questions from this domain above Q4Q6

Domain 3 Model Deployment

12%

Evaluate and implement deployment strategies like blue-green and canary rollouts using Databricks Model Serving. Register custom PyFunc models, log custom artifacts in Unity Catalog, and query models via REST API or MLflow Deployments SDK.

Sample questions from this domain above Q1Q7

FAQ

Databricks-Machine-Learning-Professional Exam FAQ

Common questions about the exam itself

What hands-on background do I need before attempting the Databricks Machine Learning Professional exam?
Databricks recommends at least one year of hands-on experience performing the machine learning tasks outlined in the exam guide. This typically includes building production ML pipelines, working with distributed training, configuring MLflow for experiment tracking, and implementing monitoring solutions. Without this foundation, the exam difficulty will make passing very challenging.
How hard is the Databricks Machine Learning Professional exam compared to the Associate level?
The Professional exam is significantly harder than the Machine Learning Associate exam. It focuses on enterprise-scale ML systems, advanced distributed computing concepts, and production MLOps practices rather than foundational tasks. Industry sources rank it as the most difficult of the seven Databricks certifications and emphasize that hands-on experience is essential to pass.
Which domain area causes most candidates the most trouble on this exam?
MLOps and drift detection using Lakehouse Monitoring typically challenge candidates the most because these areas require understanding complex monitoring architectures, statistical testing, and production deployment patterns that are less commonly practiced than basic model training. Focus on configuring monitors, interpreting drift metrics, and designing alerting systems during preparation.
How long should I realistically prepare for the Databricks Machine Learning Professional exam?
Preparation typically takes 8 to 16 weeks depending on your existing Databricks and machine learning experience. Candidates with prior experience building ML systems may prepare faster, while those transitioning from the Associate level or newer to production ML concepts should budget more time to gain hands-on experience with distributed training, MLflow, and Lakehouse Monitoring.
What happens on exam day for the Databricks Machine Learning Professional?
You have 120 minutes to answer 60 multiple-choice questions delivered online with remote proctoring. Some questions may be unscored experimental items that do not affect your score, though they are not identified during the exam. Pace yourself at roughly two minutes per question and treat all questions carefully since you cannot distinguish experimental items.
What are the retake rules if I fail the Databricks Machine Learning Professional exam?
You can retake the exam after a 14-day waiting period from your failure date, though this period is not officially published by Databricks. Each retake costs the full USD 200 exam fee with no free retakes. The 14 days gives you time to focus on weaker domains before attempting again.
How long does the Databricks Machine Learning Professional certification stay valid?
Your certification is valid for two years from the date you pass. After two years, you must retake the current version of the exam to maintain your certified status. Databricks will notify you as your expiration date approaches and requires recertification to keep skills aligned with evolving platform features.
What job roles are best suited for the Databricks Machine Learning Professional certification?
This credential is designed for Machine Learning Engineers, Data Scientists, and ML Architects who implement production-ready machine learning systems at enterprise scale. It validates your ability to design scalable pipelines, implement MLOps practices, and manage the full machine learning lifecycle on the Databricks Lakehouse Platform.
How does the Machine Learning Professional exam relate to the Machine Learning Associate exam?
The Associate exam validates foundational ML tasks like basic model training, feature engineering, and simple deployment using AutoML and MLflow. The Professional exam builds on this by requiring expertise in advanced distributed training, complex MLOps architectures, custom model serving, drift detection, and production monitoring at enterprise scale.
Are there prerequisites or other Databricks certifications I should earn first?
Databricks does not require any formal prerequisites, though the Machine Learning Associate is a natural stepping stone that builds foundational skills. The company recommends one year of hands-on ML experience, which could come from building systems on Databricks or similar platforms, making a progression through Associate level a practical pathway rather than a mandatory one.

Other Databricks Exams

Free practice questions for more Databricks certification exams

All Databricks exams