Key details for this exam, checked against the published exam outline
Each question shows the correct answer and an explanation of why it is right
Which of the following tools can be used to distribute large-scale feature engineering without the use of a UDF or pandas Function API for machine learning pipelines?
Spark ML (Machine Learning Library) is designed specifically for handling large-scale data processing and machine learning tasks directly within Apache Spark. It provides tools and APIs for large-scale feature engineering without the need to rely on user-defined functions (UDFs) or pandas Function API, allowing for more scalable and efficient data transformations directly distributed across a Spark cluster. Unlike Keras, pandas, PyTorch, and scikit-learn, Spark ML operates natively in a distributed environment suitable for big data scenarios. Reference:
Spark MLlib documentation (Feature Engineering with Spark ML).
A data scientist has developed a random forest regressor rfr and included it as the final stage in a Spark MLPipeline pipeline. They then set up a cross-validation process with pipeline as the estimator in the following code block:
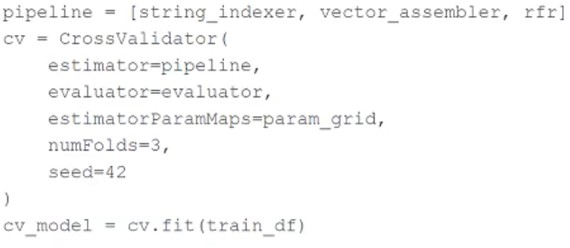
Which of the following is a negative consequence of including pipeline as the estimator in the cross-validation process rather than rfr as the estimator?
Including the entire pipeline as the estimator in the cross-validation process means that all stages of the pipeline, including data preprocessing steps like string indexing and vector assembling, will be refit or retransformed for each fold of the cross-validation. This results in a longer runtime because each fold requires re-execution of these preprocessing steps, which can be computationally expensive.
If only the random forest regressor (rfr) were included as the estimator, the preprocessing steps would be performed once, and only the model fitting would be repeated for each fold, significantly reducing the computational overhead.
Databricks documentation on cross-validation: Cross Validation
A data scientist has a Spark DataFrame spark_df. They want to create a new Spark DataFrame that contains only the rows from spark_df where the value in column discount is less than or equal 0.
Which of the following code blocks will accomplish this task?
To filter rows in a Spark DataFrame based on a condition, the filter method is used. In this case, the condition is that the value in the 'discount' column should be less than or equal to 0. The correct syntax uses the filter method along with the col function from pyspark.sql.functions.
Correct code:
from pyspark.sql.functions import col filtered_df = spark_df.filter(col('discount') <= 0)
Option A and D use Pandas syntax, which is not applicable in PySpark. Option B is closer but misses the use of the col function.
A data scientist is wanting to explore the Spark DataFrame spark_df. The data scientist wants visual histograms displaying the distribution of numeric features to be included in the exploration.
Which of the following lines of code can the data scientist run to accomplish the task?
To display visual histograms and summaries of the numeric features in a Spark DataFrame, the Databricks utility function dbutils.data.summarize can be used. This function provides a comprehensive summary, including visual histograms.
Correct code:
dbutils.data.summarize(spark_df)
Other options like spark_df.describe() and spark_df.summary() provide textual statistical summaries but do not include visual histograms.
Databricks Utilities Documentation
A data scientist wants to efficiently tune the hyperparameters of a scikit-learn model in parallel. They elect to use the Hyperopt library to facilitate this process.
Which of the following Hyperopt tools provides the ability to optimize hyperparameters in parallel?
The SparkTrials class in the Hyperopt library allows for parallel hyperparameter optimization on a Spark cluster. This enables efficient tuning of hyperparameters by distributing the optimization process across multiple nodes in a cluster.
from hyperopt import fmin, tpe, hp, SparkTrials search_space = { 'x': hp.uniform('x', 0, 1), 'y': hp.uniform('y', 0, 1) } def objective(params): return params['x'] ** 2 + params['y'] ** 2 spark_trials = SparkTrials(parallelism=4) best = fmin(fn=objective, space=search_space, algo=tpe.suggest, max_evals=100, trials=spark_trials)
Hyperopt Documentation
A data scientist wants to use Spark ML to one-hot encode the categorical features in their PySpark DataFrame features_df. A list of the names of the string columns is assigned to the input_columns variable.
They have developed this code block to accomplish this task:
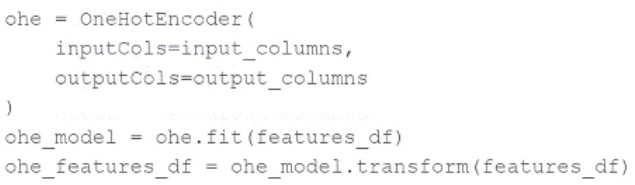
The code block is returning an error.
Which of the following adjustments does the data scientist need to make to accomplish this task?
The OneHotEncoder in Spark ML requires numerical indices as inputs rather than string labels. Therefore, you need to first convert the string columns to numerical indices using StringIndexer. After that, you can apply OneHotEncoder to these indices.
Corrected code:
from pyspark.ml.feature import StringIndexer, OneHotEncoder # Convert string column to index indexers = [StringIndexer(inputCol=col, outputCol=col+'_index') for col in input_columns] indexer_model = Pipeline(stages=indexers).fit(features_df) indexed_features_df = indexer_model.transform(features_df) # One-hot encode the indexed columns ohe = OneHotEncoder(inputCols=[col+'_index' for col in input_columns], outputCols=output_columns) ohe_model = ohe.fit(indexed_features_df) ohe_features_df = ohe_model.transform(indexed_features_df)
A machine learning engineer is trying to perform batch model inference. They want to get predictions using the linear regression model saved at the path model_uri for the DataFrame batch_df.
batch_df has the following schema:
customer_id STRING
The machine learning engineer runs the following code block to perform inference on batch_df using the linear regression model at model_uri:
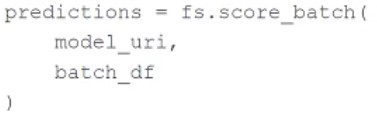
In which situation will the machine learning engineer's code block perform the desired inference?
The code block provided by the machine learning engineer will perform the desired inference when the Feature Store feature set was logged with the model at model_uri. This ensures that all necessary feature transformations and metadata are available for the model to make predictions. The Feature Store in Databricks allows for seamless integration of features and models, ensuring that the required features are correctly used during inference.
Databricks documentation on Feature Store: Feature Store in Databricks
Exam domains verified against: Official Databricks Databricks-Machine-Learning-Associate exam guide, last checked October 2026.
Master MLOps best practices and ML runtimes, including AutoML for model selection and feature engineering. Learn to create and manage feature store tables in Unity Catalog, log and track models with MLflow, and register models in the Unity Catalog registry for improved governance compared to workspace-level registries.
Sample question from this domain above: Q4
Build end-to-end ML workflows using Databricks tools and AutoML. Develop feature stores, manage model experiments with MLflow Client API, and promote models through development and production environments using aliases and tags.
Select appropriate algorithms and build training pipelines using Spark ML transformers and estimators. Master hyperparameter tuning with Hyperopt and grid or Bayesian search, apply cross-validation techniques, and evaluate models using classification metrics like F1 and ROC/AUC and regression metrics like RMSE and MAE.
Deploy models to endpoints for batch, real-time, and streaming inference. Use pandas for batch predictions, deploy custom models for real-time serving, and understand how Delta Live Tables support streaming inference workflows.
Sample question from this domain above: Q7
Common questions about the exam itself

