
Databricks Databricks-Certified-Associate-Developer-for-Apache-Spark-3.5 Practice Exam Questions & Answers
Databricks Databricks-Certified-Associate-Developer-for-Apache-Spark-3.5 Exam Details
Key details for this exam, checked against the published exam outline
- Exam Code
- Databricks-Certified-Associate-Developer-for-Apache-Spark-3.5
- Full Name
- Databricks Certified Associate Developer for Apache Spark 3.5 - Python
- Issuing Body
- Databricks
- Question Format (Our Bank)
- Multiple Choice
- Full Question Set
- 135 questions Get All Questions
Free Databricks-Certified-Associate-Developer-for-Apache-Spark-3.5 Practice Questions
Each question shows the correct answer and an explanation of why it is right
Question 1 Domain 4 Structured Streaming
A developer is trying to join two tables, sales.purchases_fct and sales.customer_dim, using the following code:
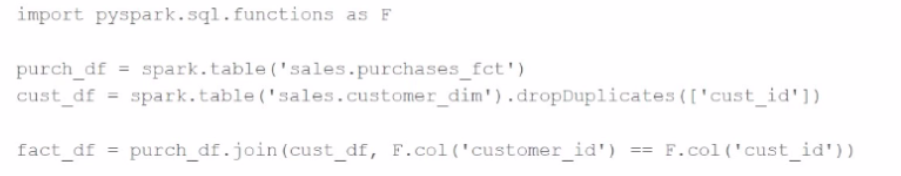
fact_df = purch_df.join(cust_df, F.col('customer_id') == F.col('custid'))
The developer has discovered that customers in the purchases_fct table that do not exist in the customer_dim table are being dropped from the joined table.
Which change should be made to the code to stop these customer records from being dropped?
In Spark, the default join type is an inner join, which returns only the rows with matching keys in both DataFrames. To retain all records from the left DataFrame (purch_df) and include matching records from the right DataFrame (cust_df), a left outer join should be used.
By specifying the join type as 'left', the modified code ensures that all records from purch_df are preserved, and matching records from cust_df are included. Records in purch_df without a corresponding match in cust_df will have null values for the columns from cust_df.
This approach is consistent with standard SQL join operations and is supported in PySpark's DataFrame API.
Question 2 Domain 3 Developing Apache Spark DataFrame/DataSet API Applications
22 of 55. A Spark application needs to read multiple Parquet files from a directory where the files have differing but compatible schemas. The data engineer wants to create a DataFrame that includes all columns from all files.
Which code should the data engineer use to read the Parquet files and include all columns using Apache Spark?
When reading Parquet files, Spark infers a unified schema automatically only if all files share identical structures. If files have different but compatible schemas, you must enable schema merging by setting the option mergeSchema=True.
Correct syntax:
df = spark.read.option('mergeSchema', True).parquet('/data/parquet/')
This option ensures Spark merges all discovered fields across Parquet files into one unified DataFrame schema.
Why the other options are incorrect:
A: Loads files but ignores extra columns --- uses only the first file's schema.
C: inferSchema applies to CSV/JSON, not Parquet.
D: mergeAllCols is not a valid Spark option.
Spark SQL Data Sources --- Parquet options (mergeSchema, path).
Databricks Exam Guide (June 2025): Section ''Using Spark DataFrame APIs'' --- reading/writing DataFrames with schema evolution and merging.
Question 3 Domain 4 Structured Streaming
3 of 55. A data engineer observes that the upstream streaming source feeds the event table frequently and sends duplicate records. Upon analyzing the current production table, the data engineer found that the time difference in the event_timestamp column of the duplicate records is, at most, 30 minutes.
To remove the duplicates, the engineer adds the code:
df = df.withWatermark("event_timestamp", "30 minutes")
What is the result?
In Structured Streaming, a watermark defines the maximum delay for event-time data to be considered in stateful operations like deduplication or window aggregations.
Behavior:
df = df.withWatermark('event_timestamp', '30 minutes')
This sets a 30-minute watermark, meaning Spark will only keep track of events that arrive within 30 minutes of the latest event time seen so far. When used with:
df.dropDuplicates(['event_id', 'event_timestamp'])
Spark removes duplicates that arrive within the watermark threshold (in this case, within 30 minutes).
Why other options are incorrect:
A: Watermarks do not remove all duplicates; they only manage those within the defined event-time window.
B: Watermark durations can be expressed as strings like '30 minutes', '10 seconds', etc., not only seconds.
D: Structured Streaming supports deduplication using withWatermark() and dropDuplicates().
Reference (Databricks Apache Spark 3.5 -- Python / Study Guide):
PySpark Structured Streaming Guide --- withWatermark() and dropDuplicates() methods for event-time deduplication.
Databricks Certified Associate Developer for Apache Spark Exam Guide (June 2025): Section ''Structured Streaming'' --- Topic: Streaming Deduplication with and without watermark usage.
Get the complete Databricks-Certified-Associate-Developer-for-Apache-Spark-3.5 question set
$20$40
Question 4 Domain 1 Apache Spark Architecture and Components
6 of 55.
Which components of Apache Spark's Architecture are responsible for carrying out tasks when assigned to them?
In Spark's distributed architecture:
The Driver Node coordinates the execution of a Spark application. It converts the logical plan into a physical plan of stages and tasks.
The Executors, running on Worker Nodes, are responsible for executing tasks assigned by the driver and storing data (in memory or disk) during execution.
Key point:
Executors are the active agents that perform the actual computations on data partitions. Each executor runs multiple tasks in parallel using available CPU cores.
Why the other options are incorrect:
A (Driver Nodes): The driver schedules tasks; it doesn't execute them.
C (CPU Cores): CPU cores execute within executors, but they are hardware, not Spark architectural components.
D (Worker Nodes): Worker nodes host executors but do not directly execute tasks; executors do.
Reference (Databricks Apache Spark 3.5 -- Python / Study Guide):
Spark Architecture Components --- Driver, Executors, Cluster Manager, Worker Nodes.
Databricks Exam Guide (June 2025): Section ''Apache Spark Architecture and Components'' --- describes the roles of driver and executor nodes in distributed processing.
Question 5 Domain 3 Developing Apache Spark DataFrame/DataSet API Applications
A data engineer needs to write a DataFrame df to a Parquet file, partitioned by the column country, and overwrite any existing data at the destination path.
Which code should the data engineer use to accomplish this task in Apache Spark?
The .mode('overwrite') ensures that existing files at the path will be replaced.
.partitionBy('country') optimizes queries by writing data into partitioned folders.
Correct syntax:
df.write.mode('overwrite').partitionBy('country').parquet('/data/output')
Question 6 Domain 1 Apache Spark Architecture and Components
An engineer notices a significant increase in the job execution time during the execution of a Spark job. After some investigation, the engineer decides to check the logs produced by the Executors.
How should the engineer retrieve the Executor logs to diagnose performance issues in the Spark application?
The Spark UI is the standard and most effective way to inspect executor logs, task time, input size, and shuffles.
From the Databricks documentation:
''You can monitor job execution via the Spark Web UI. It includes detailed logs and metrics, including task-level execution time, shuffle reads/writes, and executor memory usage.''
(Source: Databricks Spark Monitoring Guide)
Option A is incorrect: logs are not guaranteed to be in /tmp, especially in cloud environments.
B . ---verbose helps during job submission but doesn't give detailed executor logs.
D . spark-sql is a CLI tool for running queries, not for inspecting logs.
Hence, the correct method is using the Spark UI Stages tab Executor logs.
Question 7 Domain 2 Using Spark SQL
A Spark application suffers from too many small tasks due to excessive partitioning. How can this be fixed without a full shuffle?
Options:
coalesce(n) reduces the number of partitions without triggering a full shuffle, unlike repartition().
This is ideal when reducing partition count, especially during write operations.
What the Databricks Databricks-Certified-Associate-Developer-for-Apache-Spark-3.5 Exam Covers
Exam domains verified against the Official Databricks Databricks-Certified-Associate-Developer-for-Apache-Spark-3.5 exam guide, last checked November 2026.
Domain 1 Apache Spark Architecture and Components
20%Learn how Spark driver, executors, cluster manager, and SparkContext work together to distribute work across a cluster. Study execution modes, the execution hierarchy, fault tolerance, and lazy evaluation in real Spark applications.
Domain 2 Using Spark SQL
20%Work with structured data through DataFrames and Spark SQL syntax. Practice aggregations, joins, transformations, and understand how the Catalyst optimizer executes your queries.
Sample question from this domain above Q7
Domain 3 Developing Apache Spark DataFrame/DataSet API Applications
30%Build ETL workflows using the DataFrame and Dataset APIs to handle structured and semi-structured data. Apply column operations, row filtering, aggregations, and schema manipulation in real data pipelines.
Domain 4 Structured Streaming
10%Set up continuous data ingestion with Spark Structured Streaming. Master stateful and stateless operations, watermarking, output modes, checkpointing, and fault tolerance in streaming pipelines.
Domain 5 Using Spark Connect to Deploy Applications
5%Understand how Spark Connect enables remote communication and execution of Spark applications. Learn deployment patterns that enhance performance and scalability in distributed systems.
Domain 6 Using Pandas API on Apache Spark
5%Use the Pandas API on Apache Spark to run familiar Pandas operations at scale. Execute large-scale data analytics by combining Python simplicity with Spark's distributed computing.
Domain 7 Troubleshooting and Tuning Apache Spark DataFrame API Applications
10%Diagnose and debug Spark applications by inspecting execution plans and logs. Tune memory, parallelism, and configuration parameters to resolve performance bottlenecks.
Databricks-Certified-Associate-Developer-for-Apache-Spark-3.5 Exam FAQ
Common questions about the exam itself
What is the Databricks Certified Associate Developer for Apache Spark 3.5 exam really testing?
Do I need to know Spark SQL to pass the Databricks Certified Associate Developer for Apache Spark 3.5?
Is this exam harder than the older Databricks Certified Associate Developer for Apache Spark 3.0?
What should I already know before attempting the Databricks Certified Associate Developer for Apache Spark 3.5?
Which topic area in the Databricks Certified Associate Developer for Apache Spark 3.5 gives most candidates trouble?
How long should I study for the Databricks Certified Associate Developer for Apache Spark 3.5?
What happens on exam day for the Databricks Certified Associate Developer for Apache Spark 3.5?
What is the pass rate or passing score for the Databricks Certified Associate Developer for Apache Spark 3.5?
Can I retake the Databricks Certified Associate Developer for Apache Spark 3.5 if I fail?
How long does the Databricks Certified Associate Developer for Apache Spark 3.5 certification stay valid?
Other Databricks Exams
Free practice questions for more Databricks certification exams